Akarsh Jha
  • Writing
  • About
Categories
All (1)
from-scratch (1)
gpt-2 (1)
inference (1)
kv-cache (1)

Writing

LLM systems, built from scratch and measured, not asserted.

1000× Less Math, 6× Less Time

I built GPT-2 and a KV cache from scratch, then went looking for where the time actually goes.
inference
kv-cache
gpt-2
from-scratch

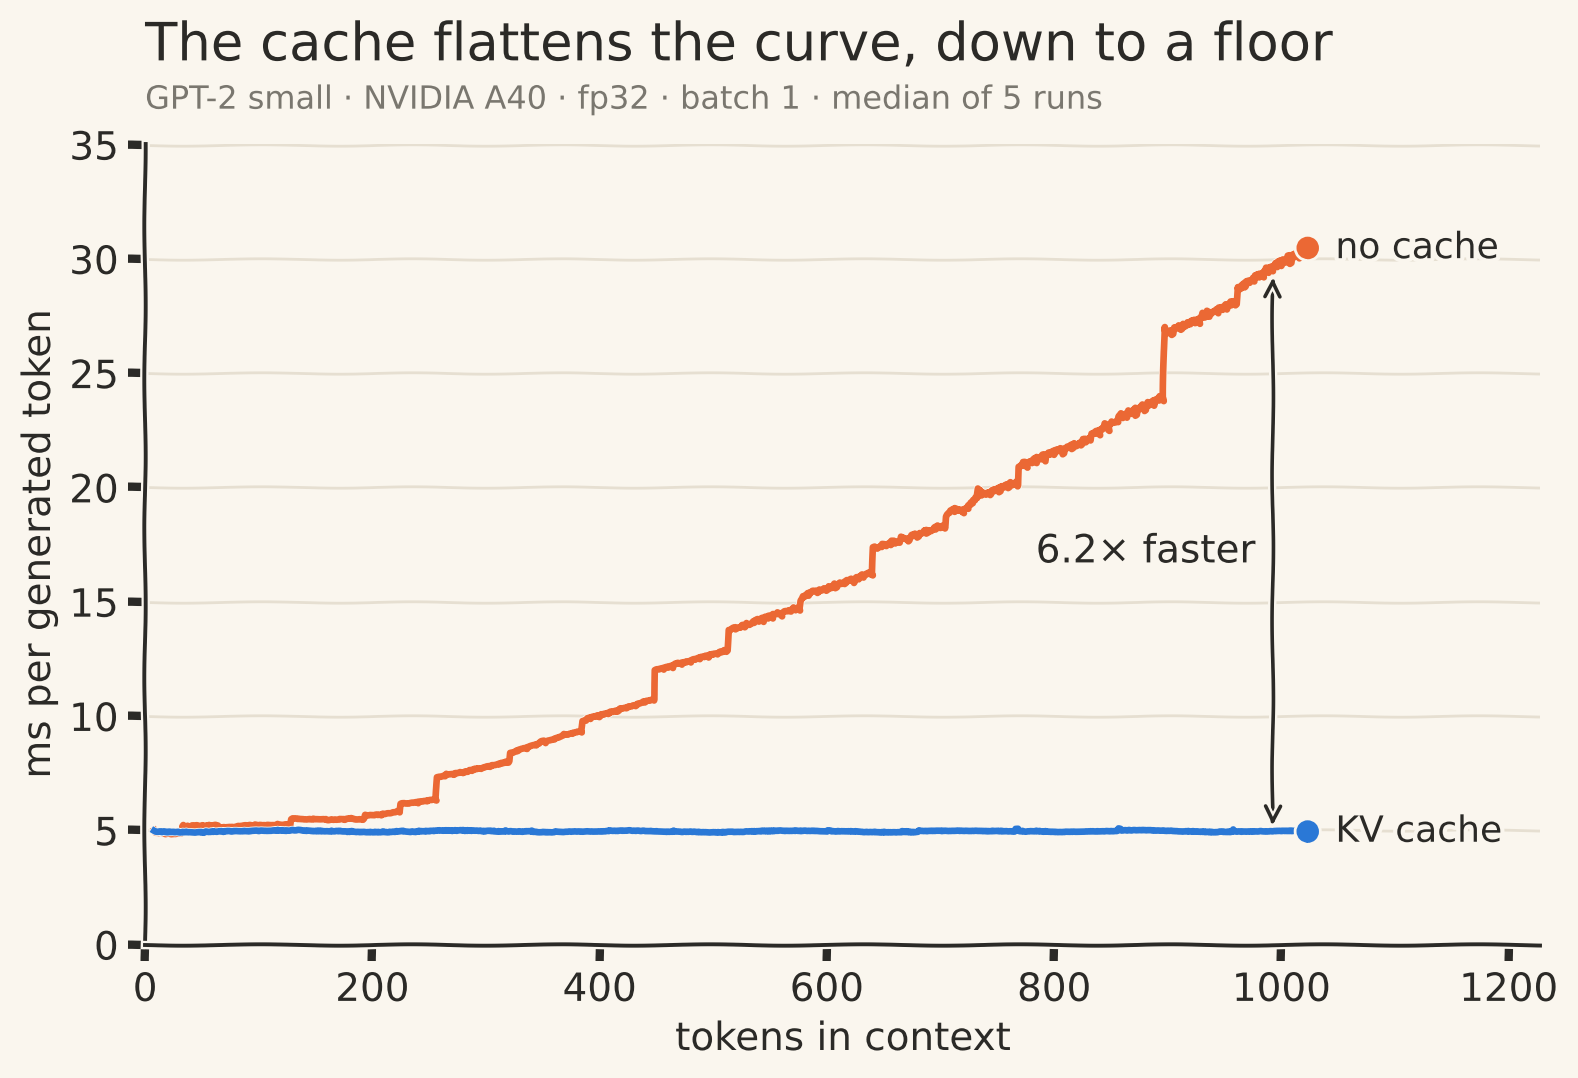
A from-scratch KV cache for GPT-2 cuts the math per token by 1000× at long context. It makes each token only 6× faster. This post measures the gap and follows it to its source.
17 October 2026
Akarsh Jha
No matching items
 

© 2026 Akarsh Jha · built with Quarto